
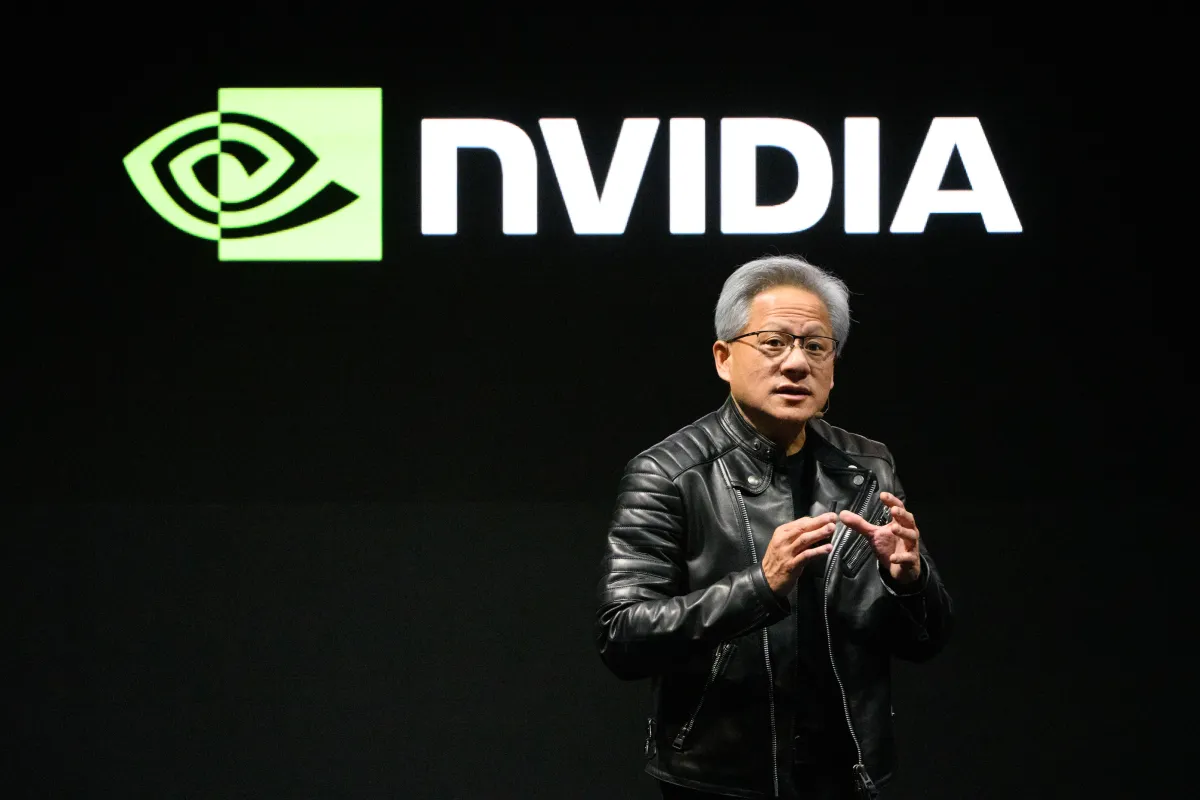
Nvidia is expanding its open AI model portfolio with a new lineup designed to power autonomous AI agents across enterprise infrastructure and personal computers. The launch reflects the company’s growing focus on making AI agents easier to deploy, customize and run locally, rather than relying exclusively on proprietary models hosted in the cloud.
The new releases include Nemotron 3.5 Super VL, a large model aimed at enterprise applications, alongside two smaller models in the Nemotron 3.5 Bolt family designed for local execution on AI-powered PCs and workstations. Nvidia says the models are optimized for agentic workflows, where AI systems must reason through multiple steps, interact with software tools and carry out tasks with limited human intervention. (TechCrunch)
Nemotron 3.5 Super VL comes with 120 billion parameters and targets demanding business applications. Despite being smaller than Nvidia’s Nemotron 3 Ultra, which has 550 billion parameters, the company claims Super VL can deliver comparable accuracy on instruction-following and tool-use tasks.
Nvidia says the model can outperform competing systems from OpenAI and Anthropic on selected agentic workloads when post-trained for specific tasks. These include document analysis, financial accounting, scientific experimentation, medical insurance claims and cybersecurity resilience. Such performance claims depend on the benchmarks and configurations used, but they illustrate how AI competition is increasingly focused on specialized business tasks rather than general-purpose chatbot performance alone.
The model has already attracted interest from several established companies. Nvidia identifies Skydance, EY, Ramp, CrowdStrike, Perplexity and Salesforce among the organizations using Super VL, suggesting that the company sees enterprise adoption as a key driver of growth for its open-model strategy.
The smaller Bolt models target a different market: running AI agents directly on local hardware. Nemotron 3.5 Bolt 74B-A9B is a 74-billion-parameter model designed to balance reasoning capabilities with speed and memory efficiency. Nvidia says it can handle multistep reasoning, web browsing and tool calling, making it suitable for assistants that need to perform tasks directly on a user’s computer.
The smallest model, Nemotron 3.5 Bolt E4B, is designed primarily for conversational agents. Nvidia said Super VL and Bolt 74B-A9B are available now, while Bolt E4B is expected to arrive later in October. (TechCrunch)
The releases are closely connected to Nvidia’s push into a new generation of AI PCs and workstations. Its RTX Spark-powered systems are designed to run AI workloads locally, while DGX Spark workstations target developers and professionals who need more computing capacity. Nvidia is working with hardware and software partners, including Microsoft and Dell, to bring these systems and their supporting ecosystem to market.
Running AI models locally can offer several advantages. Organizations may gain more control over sensitive data, reduce dependence on external API providers and avoid paying for every model interaction. Local execution can also make AI agents more practical for continuous tasks that need to operate in the background. However, performance still depends on the available hardware, memory requirements and the complexity of the model being used.
For enterprises, the appeal of open-weight models extends beyond cost. Companies can adapt models to their own data, customize them for specific workflows and deploy them on infrastructure they control. Nvidia argues that this flexibility allows businesses to build specialized AI systems without being locked into a single proprietary provider.
That strategy is becoming increasingly important as the AI industry evolves. OpenAI and Anthropic continue to develop powerful proprietary models, but businesses are also exploring alternatives that offer more control over deployment and operating costs. At the same time, major AI developers are diversifying their hardware requirements, considering processors from companies such as Amazon and Cerebras alongside Nvidia’s GPUs, while some are developing their own chips.
Nvidia’s position is therefore more complex than simply supplying the hardware behind the AI boom. By releasing open-weight models and software tools alongside its chips, the company is attempting to make its infrastructure more attractive to businesses building their own AI systems.
The strategy also creates an opportunity to extend Nvidia’s reach beyond centralized data centers. If increasingly capable agents can run on personal computers and enterprise workstations, AI computing could become a more distributed part of everyday work, from software development and research to finance and business operations.
The biggest challenge will be proving that these models can deliver reliable results across real-world workloads while remaining efficient enough to justify local deployment. Enterprise customers will also need to address security, governance and oversight as AI agents gain greater access to internal systems and sensitive information.
Still, Nvidia’s latest launch signals where the company believes the market is heading. The next phase of AI adoption may depend not only on building more powerful models, but also on giving organizations the freedom to customize them, run them on their own infrastructure and turn them into agents that can perform useful work around the clock.
Leave a Reply